
Anthropic & Accenture: AI Embedded Evaluation
Anthropic named Accenture its first embedded AI evaluator in a $2B deal. Here's what independent AI auditing means for enterprise safety and your business.
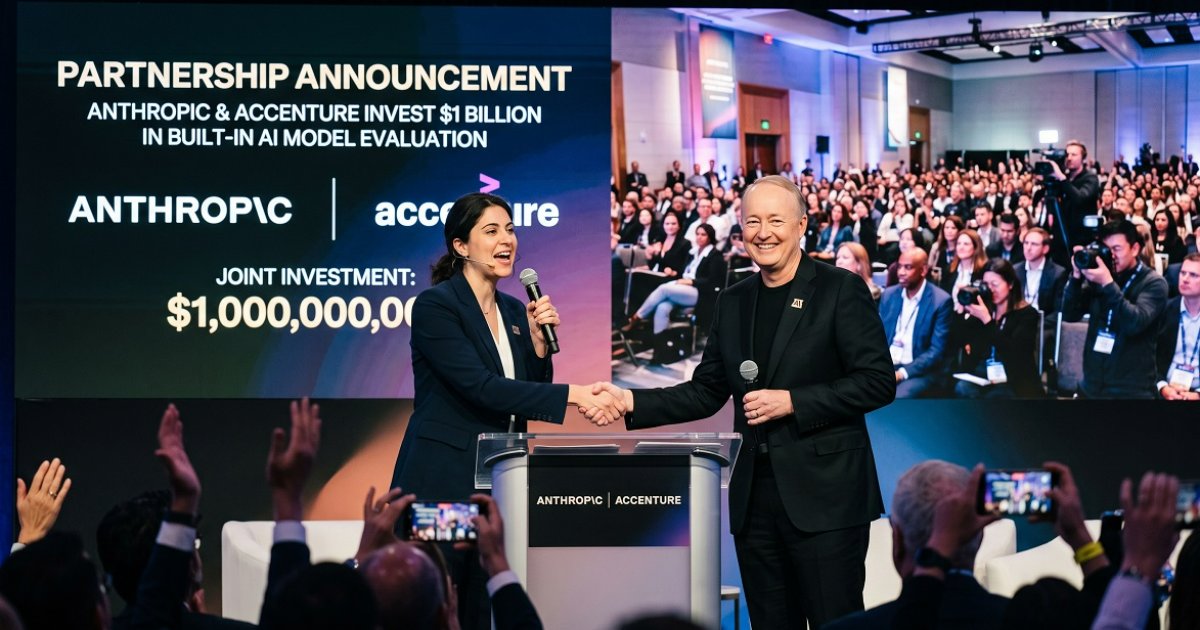
The $2 Billion Bet on AI You Can Actually Trust
Both Anthropic and Accenture have each committed to investing at least $1 billion over five years — a combined $2 billion — to build what they are calling a new model for frontier AI safety oversight. That figure isn't a marketing budget. It's the price tag on a structural answer to a question every enterprise AI buyer has been quietly asking: who watches the model?
The answer, it turns out, is someone who sits at a desk inside the lab, holds an access badge, and works for a different company. What that arrangement means for how AI gets deployed in business — and why the timing matters more than most coverage has acknowledged — is what this article is about.
What "Embedded Evaluation" Actually Means
The term sounds technical, but the concept has a clear precedent. Amodei himself pointed to it in his September 12, 2026 essay "We Must Pace the Frontier": the banking industry has long placed regulatory supervisors inside financial institutions, giving them employee-level access to verify that risk practices match public commitments. Embedded AI evaluation is the same logic applied to frontier models.
On September 18, 2026, Anthropic and Accenture formally announced a partnership to establish a team of embedded evaluators working alongside Anthropic's internal teams. The evaluators — drawn from Faculty, Accenture's specialist AI business — will evaluate and red-team models, conduct alignment assessments, and test model safeguards. Critically, they will have ongoing access to permissions and tools comparable to those of internal employees doing equivalent risk assessments: desks in Anthropic's offices, access badges, and company laptops.
This is not a periodic external audit. It is continuous, inside-the-building oversight by people who are not on Anthropic's payroll.
Independent evaluation isn't a checkbox. It's the difference between a fire drill and a fire marshal who never leaves the building.
Why Faculty, and Why Now
Accenture acquired Faculty — one of the world's leading applied AI companies — specifically to build deep technical safety capacity. Faculty's track record spans government, defense, healthcare, and critical infrastructure, including development of the UK National Health Service's Early Warning System during the COVID-19 pandemic. That history matters: this is not a consulting team learning AI safety on the job. It is an organization that has spent years building complex AI systems designed to be safe by construction, not patched for safety after the fact.
The timing is equally deliberate. Amodei's essay landed six days before the partnership announcement, and it was not a coincidence. The essay introduced a three-step framework — embedded evaluators, democratic coordination among AI labs, and eventual global coordination — with embedded evaluation as the only step Anthropic committed to unilaterally. The Accenture deal is the first concrete implementation of that commitment.
The Access Question
What makes this arrangement structurally different from conventional third-party audits is the depth of access. Conventional audits are retrospective: an external team reviews documentation, runs tests on released models, and produces a report. Embedded evaluation is prospective and continuous — evaluators are present during training pipeline decisions, not just after the model ships.
Amodei's framework specifies that embedded evaluators should be able to verify adherence to safety practices, report incidents, and assess the alignment of training pipelines and processes — not just completed models. That scope is significantly broader than anything the enterprise AI market has seen formalized before.
Why This Changes the Enterprise AI Calculus
For a CEO or COO deploying AI in critical business processes — procurement approvals, compliance workflows, financial controls — the question has never really been "does this model perform well on benchmarks?" It has been: "if this model makes a consequential error, who is accountable, and how would I even know?"
That question has been structurally unanswerable until now. AI labs self-certify. Safety cards are written by the same teams that built the model. Red-teaming is conducted internally, with results disclosed selectively. The enterprise buyer has had no independent signal to rely on.
Embedded evaluation changes that architecture. When an independent team with employee-level access is continuously assessing a model's behavior — including its alignment with human values, not just its benchmark scores — the enterprise buyer gains something genuinely new: a third-party signal that is structurally separated from the lab's commercial incentives.
The enterprise AI buyer has spent three years making deployment decisions without an independent signal. That gap is now closing — and the companies that understand what it means will move faster than those still waiting for certainty.
The Accountability Gap in Enterprise AI Deployments
Consider what happens when an AI agent makes an error in a high-stakes process. A procurement agent approves a vendor that should have been flagged. A compliance workflow misclassifies a transaction. A contract review tool misses a liability clause. In each case, the business carries the operational and legal consequence. The model vendor carries almost none.
This asymmetry has been the quiet brake on enterprise AI adoption at scale. Boards and legal teams have been right to be cautious — not because AI doesn't work, but because the accountability architecture around it has been immature. Embedded evaluation is the first structural response to that immaturity that comes from inside a frontier lab rather than from a regulator.
For businesses already exploring AI agent architectures — the kind that remove human bottlenecks from procurement and approval workflows — this shift in the oversight model is directly relevant to the risk conversation with your board.
What the $2 Billion Signal Tells You
The combined investment figure is worth pausing on. Neither Anthropic nor Accenture is treating this as a pilot program or a PR exercise. At $1 billion each over five years, both organizations are building institutional capacity — hiring, tooling, process design — that will outlast any single model release cycle.
That scale of commitment signals something to the enterprise market: safety evaluation is becoming infrastructure, not a feature. Just as cloud providers built redundancy and uptime guarantees into their core offering because enterprise buyers demanded it, AI labs are now building independent oversight into their development process because the alternative — self-certification at frontier capability levels — is no longer credible.
Anthropic has also been explicit that the partnership is non-exclusive. The company expects to announce additional evaluators in the coming weeks, and Accenture is expected to work with other AI developers in similar capacities. The goal, as stated in the official announcement, is an ecosystem of evaluators operating with shared standards — not a bilateral arrangement between two companies.
What Businesses Should Do With This Information
The Anthropic-Accenture partnership is not something most businesses will interact with directly. You are not hiring Faculty. You are not embedded inside Anthropic's offices. But the framework it establishes has direct implications for how you should evaluate and procure AI systems going forward.
Reframe Your Vendor Due Diligence
The standard enterprise AI procurement checklist — SOC 2 compliance, data residency, uptime SLAs — was designed for software, not for systems that reason, decide, and act. A model that passes a SOC 2 audit can still produce systematically biased outputs, hallucinate in domain-specific contexts, or behave differently under adversarial inputs than it does in a demo environment.
The question to add to your vendor conversations is direct: does an independent third party have ongoing access to evaluate this model's behavior, and can you show me their findings? That question will separate vendors who have thought seriously about accountability from those who haven't. It is also the question your board and legal counsel will eventually ask you — better to have the answer before they do.
Executives who can walk into a board meeting and explain not just what their AI systems do, but how those systems are independently verified, are the ones who turn AI adoption from a liability conversation into a competitive advantage narrative. That shift in how you're perceived — from someone taking a technology risk to someone managing it with rigor — is worth more than any single efficiency gain.
Understand the Difference Between Safety and Compliance
These two concepts are often conflated in enterprise AI conversations, and the conflation is costly. Compliance means meeting a defined standard — a checklist, a regulation, a certification. Safety means the system behaves as intended across the full distribution of real-world inputs, including edge cases the checklist didn't anticipate.
Embedded evaluation is designed to close the gap between the two. A model can be fully compliant with every current AI regulation and still fail in ways that compliance frameworks haven't yet defined. The value of continuous independent evaluation is precisely that it operates ahead of the regulatory curve — catching failure modes before they become incidents.
For businesses in regulated industries — financial services, healthcare, legal — this distinction is not academic. The risks of deploying AI systems without independent verification are asymmetric: the upside of faster deployment is incremental, the downside of a high-profile failure is reputational and potentially legal.
Build Internal Evaluation Capacity in Parallel
The Anthropic-Accenture model is designed for frontier labs. But the underlying principle — that the people building a system should not be the only people evaluating it — applies at every scale of AI deployment.
If your organization is deploying AI agents in critical workflows, the minimum viable version of this principle is a structured internal review process that is organizationally separated from the team that built or selected the system. That means someone in your risk, compliance, or operations function owns the evaluation process — not the technology team that championed the deployment.
This is not bureaucracy for its own sake. It is the same logic that separates the CFO function from the business units whose numbers the CFO audits. Independence is the mechanism that makes the signal credible.
When that structure is in place, something shifts for the people running the business: the constant background anxiety about whether the AI is doing what it's supposed to do gets replaced by a process. That's not a small thing. Operational calm — the ability to make decisions about AI deployment from a position of verified confidence rather than educated guessing — is what allows leadership to focus on strategy instead of firefighting.
FAQ
What is embedded AI evaluation, and how is it different from a standard audit? An embedded evaluator has continuous, employee-level access to an AI lab's systems, processes, and training pipelines — not just access to completed models after release. A standard audit is retrospective and periodic; embedded evaluation is ongoing and prospective, covering alignment assessments and safety practices in real time.
Why did Anthropic choose Accenture as its first embedded evaluator? Accenture brings Faculty, its specialist AI business, which has an established track record evaluating models for major AI labs and building safety-by-design systems across government, defense, and healthcare. The partnership is non-exclusive — Anthropic has indicated it will announce additional evaluators, and Accenture is expected to work with other AI developers in similar roles.
How much are Anthropic and Accenture investing in this program? Each company has committed to investing at least $1 billion over five years, for a combined minimum of $2 billion dedicated to building embedded evaluation capacity. Anthropic is funding Accenture's work directly, while also exploring longer-term pooled or government funding models for the broader evaluator ecosystem.
Does this partnership affect businesses that use Claude or Anthropic's API? Not directly — but it changes the accountability architecture around the models you're deploying. Independent evaluation of the model's alignment and safeguards provides a third-party signal that was previously unavailable to enterprise buyers, which is relevant to any risk or compliance conversation about AI deployment.
Is embedded evaluation a regulatory requirement? Not yet. Anthropic committed to this step unilaterally, and called on governments to require other frontier labs to match it. As of the announcement date, no binding regulation mandates embedded evaluation — but the framework is being designed to be compatible with future regulatory requirements, and the precedent from financial services regulation suggests that voluntary adoption often precedes mandatory standards.
What should a business do right now in response to this development? Update your AI vendor due diligence process to include questions about independent evaluation. Build internal review processes that are organizationally separated from the teams deploying AI. And treat the Anthropic-Accenture model as a preview of where enterprise AI accountability standards are heading — not as a distant development that doesn't affect your procurement decisions today.
The Anthropic-Accenture partnership is early-stage — implementation details are still being worked out, and the field of embedded evaluation has no settled standards yet. But the direction is clear. Independent, continuous oversight of AI systems is moving from aspiration to infrastructure. The businesses that build their AI governance frameworks around that reality now — rather than waiting for regulation to force the issue — will be the ones with the cleaner board conversations, the faster deployment cycles, and the competitive advantage that comes from being trusted with consequential decisions.
If you want to understand how independent AI evaluation frameworks apply to your specific deployment context, book a 15-minute consultation.
Have questions? Ask the AI agent right now
Responds in seconds, knows everything about our services and will help with your situation
You might also like
An AI Hallucination Almost Started a War
AI hallucinations aren't just a technical bug. They can trigger real-world crises. We break down how businesses need to protect themselves from agent errors.
EnterpriseVals & a16z: How AI Benchmarks Now Decide Everything
Vals and a16z are rewriting the rules of AI agent evaluation — why benchmarks now determine which vendors enterprises choose, and what the cost of getting that choice wrong looks like.
EnterprisePrompt Injection in GPT-6 Astra: Finance Risk
OpenAI confirmed GPT-6 Astra still fails 8.5% of indirect prompt injection tests. Here's what that means for your financial data and how to protect it.