
Inside a Self-Analyzing AI Lead-Qualification Chatbot
A technical breakdown of a production AI chatbot: deferred mounting for PageSpeed, input validation tuned on real conversations, UTM attribution, and a built-in quality-analytics layer — with real production numbers.
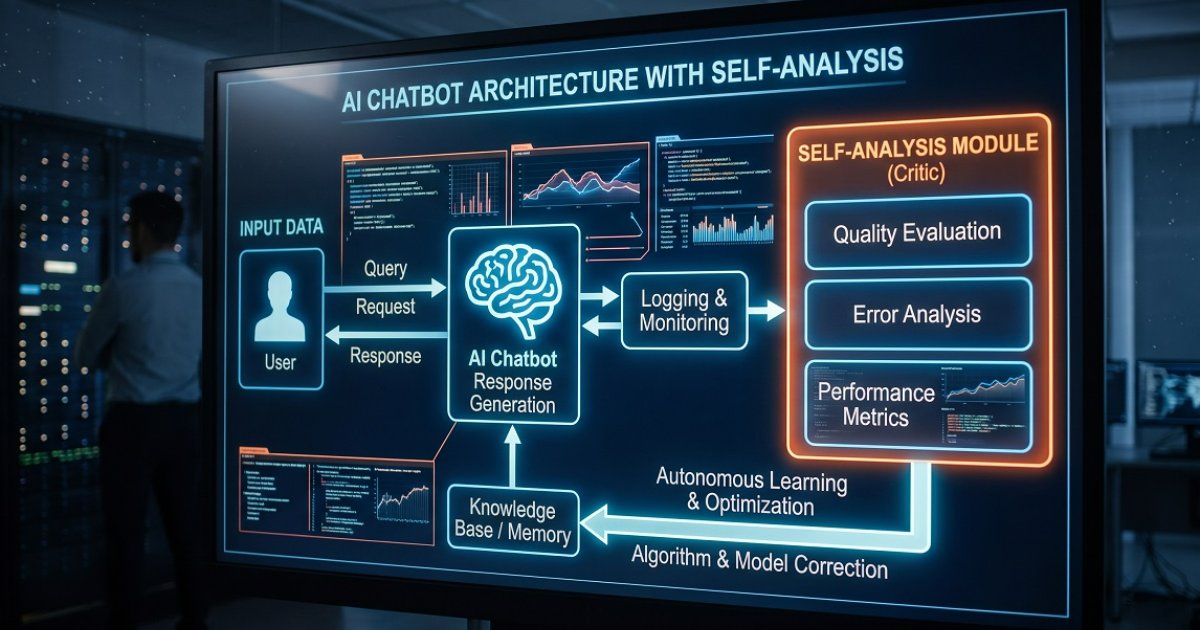
The chatbot nobody has time to manually audit
The usual problem with website AI chatbots is that they're a black box. You install the widget, it appears to respond, but whether it's actually converting visitors into leads stays unknown until someone manually reads through the logs. Once there are thousands of logs, that "someone" never gets to it.
Here's a technical walkthrough of how a production AI lead-qualification agent is actually built — from performance engineering down to a layer that monitors its own quality. Real production numbers, not a demo.
The problem
A static "name + phone" form gives sales nothing but a contact. The AI agent needed to do something different: run a short, natural dialogue — one question at a time — and hand sales an already-structured lead with context on the client's industry and pain point, not a bare phone number. That's a fundamentally different task than a simple reply-bot — the distinction is broken down in Telegram Bot vs AI Agent: What's the Real Difference?
Performance: the heaviest component on the site, with zero PageSpeed cost
The chatbot component is the heaviest piece of client-side JS on the site. Mounting it immediately on page load means shipping and parsing that code for 100% of visitors, most of whom never open the chat at all.
The fix: deferred mounting. The component only renders a couple of seconds after the initial page load, after the critical content has already painted.
// DeferredChatBot.tsx — simplified
export default function DeferredChatBot() {
  const [ready, setReady] = useState(false);

  useEffect(() => {
    const timer = setTimeout(() => setReady(true), 2000);
    return () => clearTimeout(timer);
  }, []);

  if (!ready) return null;
  return <SimpleAIChatBot />;
}
Result in production: 91/100 (desktop) and 94/100 (mobile) on Google PageSpeed — with the chatbot active on every page.
Input validation tuned on real conversations
The first version of the bot was too strict, blocking messages with typos or non-standard phrasing. After reviewing real conversations, validation was recalibrated separately for the opening message versus an already-running dialogue:
const spamPatterns = [
  /^(.)\1{6,}$/,          // 7+ repeated characters
  /^[qwertyuiop]+$/i,     // top keyboard row
  /^[йцукенгшщзх]+$/i,    // Ukrainian keyboard layout
  // ...a handful more gibberish/spam patterns
];

const isDialogWithAgent = messages.length > 0;
if (isDialogWithAgent) {
  // Mid-conversation: tolerant validation — typos and informal
  // replies pass through, only obvious spam is blocked
  return true;
}
One specific case from real dialogues: when a user gave a vague reply like "all of it," the agent used to pick a problem from its own template — and users would correctly push back. The fix was a specific rule: on a vague answer, the agent asks which problem costs the most time instead of guessing.
Attribution: every lead knows where it came from
Every CTA button on the site writes its own utm_campaign to sessionStorage before the chat even opens. When a lead is submitted, those tags travel with the conversation into the CRM (Google Sheets) and GA4 — so it's not just "how many leads," but exactly which button, page, or partner link each one came from.
The core piece: a dashboard that analyzes its own quality
A dedicated service reads the raw logs of every AI response (success / fallback / response time / customer message text) and turns them into ready-made insights — without anyone manually reading a single conversation. It's a concrete answer to the broader question of how to measure real AI agent autonomy in business:
| What the system tracks | Why |
|---|---|
| Success / fallback rate | Whether the model is really answering, or falling back often |
| Average response time | Whether customers are losing patience |
| Most common customer pain points | Auto-extracted keywords from real messages |
| Peak activity hours | When the chatbot is actually needed most |
| Auto-generated recommendations | e.g. "fallback rate > 20% → review prompts" |
const successRate = Math.round(
  (successfulResponses.length / totalResponses) * 100
);

if (fallbackRate > 20) {
  recommendations.push(
    'Optimize the API connection and prompts to reduce fallback mode.'
  );
}
Real production numbers
| Metric | Value |
|---|---|
| Structured leads captured | 53 |
| AI success rate (non-fallback) | 88% |
| Average response time | 3.8s |
| Average messages to a completed consultation | 4.9 |
| PageSpeed (desktop / mobile) with chatbot active | 91 / 94 |
Takeaway
A chatbot that just "seems to work" and one that reports on its own quality are two different categories of product. The second lets you make decisions about prompts, chat UX, or qualification logic based on data instead of guesswork. What it actually costs to build something like this for a specific business is broken down in Custom AI Agent Development Cost: What You Actually Pay For.
Have questions? Ask the AI agent right now
Responds in seconds, knows everything about our services and will help with your situation
You might also like
How AI-Generated Content Gets Fact-Checked Before It Publishes
A technical breakdown of a guardrail layer that automatically cross-checks every claim in AI-written text against its source and live search, fixes what it can't verify, and keeps a correction log — before a reader ever sees it.
Technical GuidesRAG vs CAG: Which AI Architecture Fits Your Business
RAG vs CAG explained for business leaders: how each architecture works, when to use which, and a real case with numbers to guide your AI decision.
Technical GuidesQwen3Guard: Real-Time AI Content Safety
Alibaba's free open-source Qwen3Guard filters toxic tokens in real time. Here's how SaaS teams and CTOs can deploy it to protect LLM-powered products.