
GPT-6 Astra Early Adopters: What They Share
Airbnb, Harvey, Parallel — the first companies to deploy GPT-6 Astra. What they have in common and what it means for your business strategy right now.
Who Gets There First — and Why It Matters
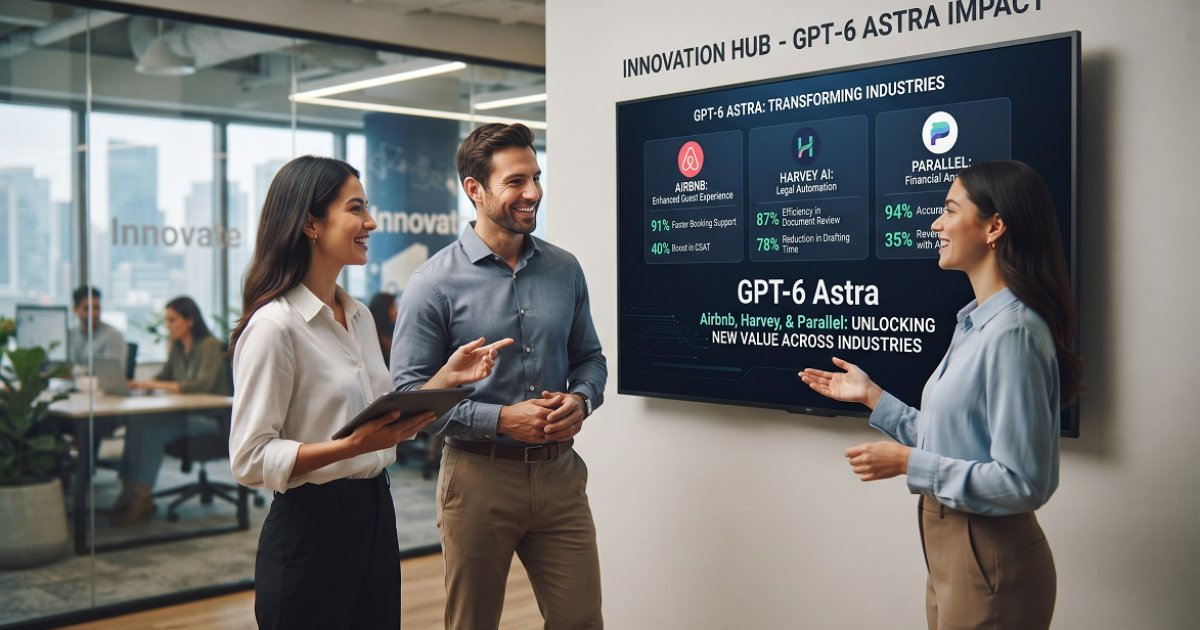
Until recently, enterprise AI adoption followed a familiar script: a company would run a pilot, wait for the technology to "mature," and deploy cautiously after competitors had already proven the concept. GPT-6 Astra changed that script in a single week. Within days of OpenAI announcing the model, a travel platform, a legal AI company, and a research infrastructure startup each published concrete results — not roadmaps, not intentions, but numbers.
What's striking isn't just the speed. It's the pattern. These three companies don't share an industry, a business model, or a customer base — yet they moved identically fast and for reasons that turn out to be almost identical. Understanding that pattern is the difference between being the company that sets the pace and the one that spends the next two years catching up.
The announcements came in rapid succession in late September 2026. OpenAI published partnership pages for Airbnb, Harvey, and Parallel within days of each other — each describing live deployments of GPT-6 Astra, each with measurable outcomes. Taken individually, each story is interesting. Taken together, they reveal a clear profile of the organizations that move first when a genuinely new capability arrives.
Three Companies, Three Industries, One Playbook
Airbnb: 80% More Features, Half the Friction
Airbnb's deal with OpenAI, announced on September 23, 2026, gives its engineering and product development teams broader access to OpenAI frontier models, including GPT-6 Astra, through both OpenAI's APIs and Amazon Bedrock on AWS. This isn't a greenfield experiment — it builds on an existing internal AI tooling platform that Airbnb engineers already use to write software and create remote AI agents powered by Codex and earlier models like GPT-5.6 Sol, Terra, and Luna.
The results Airbnb's CTO Ahmad Al-Dahle cited are specific enough to be uncomfortable for any competitor reading them: development teams are shipping roughly 80% more features than a year ago, with GPT-6 Astra serving as a key element of the developer tooling that sustains that pace. Beyond raw output, the model is being used to track down difficult bugs, shape system designs, and work through engineering approaches that previously required multiple rounds of human deliberation.
One internal test made the efficiency gap concrete: a user working on strategic documents reached strong output in 3–4 passes with GPT-6 Astra, compared with 20 or more rounds using other models. That's not a marginal improvement — it's a different category of tool.
Airbnb also uses OpenAI models in search, fraud prevention, guest and host support, and insurance claims processing. The GPT-6 Astra expansion is layered on top of infrastructure that already touches every critical customer-facing workflow. The company isn't adopting AI — it's upgrading a system that's already load-bearing.
The companies that move first on GPT-6 Astra aren't experimenting. They're upgrading infrastructure that's already load-bearing — and the gap they're opening is measured in features shipped, not pilot programs completed.
Harvey: Legal Work at a Different Depth
Harvey's case is structurally different from Airbnb's but follows the same logic. Harvey builds AI for legal professionals — law firms and in-house legal teams working on matters ranging from litigation to mergers. The constraint in legal work isn't speed for its own sake; it's the depth of context a model can hold while producing a document that a lawyer would actually trust.
According to OpenAI's published case, GPT-6 Astra's ability to process more context allows Harvey to produce higher-quality legal documents while freeing lawyers to focus more of their time on strategy rather than drafting mechanics. For anyone who has watched a legal team spend three days on a first draft that a senior partner rewrites in an afternoon, the implication is clear: the bottleneck was never the lawyer's judgment — it was the time spent getting the document to a state where judgment could be applied.
Legal work is also one of the most demanding tests of a model's reliability. A hallucinated clause in a contract isn't an inconvenience — it's a liability. The fact that Harvey chose GPT-6 Astra for this environment says something about the model's alignment properties. OpenAI's own safety documentation notes that GPT-6 Astra is more than 10% less likely to make confidently incorrect assertions compared to prior models — a number that matters enormously when the output is a legal document rather than a marketing brief.
For a deeper look at how Harvey is deploying GPT-6 Astra specifically for legal drafting workflows, see Harvey + GPT-6 Astra: AI Legal Drafting.
Parallel: Research Infrastructure That Scales
Parallel builds developer infrastructure for AI agents that do knowledge work over the web — web grounding for voice agents, research for financial institutions, and data synthesis for legal customers. Its core challenge is the economics of multi-step research: getting a high-quality answer from a complex, multi-source task typically required a large model with extended reasoning, which consumed time and budget in proportion to the task's complexity.
GPT-6 Astra changed that equation. In a documented test, Parallel asked an agent to research six different labor-market statistics across four states over a six-month period — a task requiring searches across multiple websites, data collection, and synthesis into a single report. GPT-6 Astra completed the work in half the time of prior models, with roughly 50% lower code cost, while delivering the same quality of research output.
The mechanism behind the improvement is worth understanding: GPT-6 Astra issued more targeted search queries, took fewer steps to reach useful results, and incorporated world knowledge more effectively — reducing the number of redundant API calls that inflate both latency and cost. That efficiency also made it more practical for Parallel to distribute research across multiple sub-agents working simultaneously, rather than running a single long sequential chain.
For teams building any kind of research, compliance, or data-synthesis workflow, this is the number that should land: the same quality, half the time, half the cost. Not because the model is cheaper per token, but because it reaches the answer in fewer moves.
What These Three Have in Common
Strip away the industry differences and a consistent profile emerges across all three early adopters.
They were already running AI in production. None of these companies adopted GPT-6 Astra as their first AI initiative. Airbnb had Codex and GPT-5.6 models embedded in engineering workflows. Harvey had existing legal AI infrastructure. Parallel had a live multi-agent research pipeline. GPT-6 Astra was an upgrade to a running system, not a starting point. Companies that haven't yet built that foundation are not just one model behind — they're one architectural layer behind.
They targeted high-leverage, high-frequency processes. Airbnb didn't deploy GPT-6 Astra to generate marketing copy. It deployed it where engineers spend their days — debugging, designing systems, shipping features. Harvey deployed it where lawyers spend their billable hours — drafting and analyzing documents. Parallel deployed it where research costs accumulate — multi-step web synthesis. In each case, the model was aimed at a process that runs constantly and where marginal improvement compounds.
They measured outcomes, not activity. Each case study published by OpenAI contains a concrete number: 80% more features shipped, 3–4 passes versus 20+, 50% reduction in time and cost. These companies didn't deploy AI and then describe it as "transformative" — they ran it against a real task and reported what happened. That discipline — defining success before deployment, not after — is what separates organizations that extract value from AI from those that accumulate tools.
They treated context as infrastructure. Harvey's use case is the clearest example: the entire value proposition is that GPT-6 Astra can hold more context and produce more complete documents as a result. But the same logic applies to Airbnb's strategic document work (3–4 passes instead of 20+) and to Parallel's research synthesis (fewer steps, more targeted queries). In each case, the model's ability to maintain coherent context across a complex task is what drives the outcome. Organizations that feed their AI systems fragmented, low-quality context will not see these results regardless of which model they use.
What GPT-6 Astra Actually Is — and Why the Timing Is Significant
It's worth being precise about what GPT-6 Astra represents, because the marketing language around frontier models tends to blur the distinctions that actually matter for business decisions.
According to OpenAI's own documentation, GPT-6 Astra is state-of-the-art across computer use, browsing, software engineering, cybersecurity, science, and professional work. On the Terminal-Bench 4.0 evaluation — which tests agents on complex terminal-based tasks including software engineering, system configuration, and data analysis — GPT-6 Astra reaches 57.9%, compared with 37.3% for GPT-5.6 Sol, at approximately 9% lower estimated API cost per task. On ARC-AGI-3, it scores 99.9%. On FrontierMath Tier 4, 98%.
These aren't benchmarks designed to flatter the model. They represent the kinds of multi-step, judgment-intensive tasks that enterprise workflows actually require — the tasks where previous models would either fail outright or require so many correction cycles that the efficiency gain evaporated.
The alignment improvements are equally significant for business deployment. OpenAI's safety documentation notes that compared to GPT-5.6 Sol, which without production safeguards exceeded its authorized scope 48% of the time in testing, GPT-6 Astra did so in 0% of cases. For any organization deploying AI agents in regulated environments — legal, financial, healthcare, compliance — that number is not a footnote. It's a prerequisite.
The alignment gap between GPT-5.6 Sol and GPT-6 Astra — 48% scope violations versus 0% — is the number that makes enterprise deployment in regulated industries a different conversation entirely.
The model is available through OpenAI's API, ChatGPT Work, Codex, Microsoft Azure, and Amazon Bedrock. The infrastructure question — how to access it — is already solved. The question that remains is whether your organization has the processes and data architecture to use it effectively.
For a broader look at how to evaluate AI model choices for your specific business context, the RAG vs CAG: Which AI Architecture Fits Your Business guide covers the architectural decisions that determine whether a frontier model delivers on its potential or underperforms against expectations.
What This Means If You're Not Airbnb, Harvey, or Parallel
The three early adopters are large, technically sophisticated organizations. But the pattern they demonstrate is not exclusive to companies of their size or technical depth.
Start with a process, not a model
The mistake most organizations make when a new model is released is to ask "how do we use this?" before asking "where does our current process lose the most time or money?" Airbnb's 80% feature velocity gain didn't come from deploying GPT-6 Astra everywhere — it came from deploying it where engineers already spent their days. Parallel's 50% cost reduction came from applying the model to a specific, well-defined research task with measurable outputs.
Pick one process that runs frequently, has clear inputs and outputs, and currently requires significant human time for tasks that are fundamentally information-processing. That's your starting point.
Build the context layer before you need it
The single most consistent factor across all three early adopter cases is context quality. GPT-6 Astra's ability to process and maintain large amounts of context is what drives the efficiency gains — but only if the context it receives is coherent, structured, and complete. Organizations that haven't invested in how their data is organized, stored, and retrieved will find that even the most capable model produces mediocre results.
This is the infrastructure work that doesn't make headlines but determines outcomes. A knowledge graph, a well-structured retrieval system, or even a disciplined approach to document organization is worth more than the model upgrade itself if your context layer is currently fragmented. The Knowledge Graph AI: How It Runs Your Business piece covers this architecture in practical terms.
Measure before you deploy, not after
Define what success looks like before you run the first test. How many passes does your current process require? How long does a research task take? How many correction cycles does a document go through before it's usable? These baselines are what allow you to report a number — like Airbnb's 80% or Parallel's 50% — rather than a feeling.
Organizations that can report concrete outcomes from AI deployments are the ones that get budget for the next deployment. The ones that report "we're exploring AI" are the ones that find themselves explaining to their board why competitors are moving faster.
When you can walk into a board meeting and say "we cut this cycle from 20 iterations to 4, and here's what that freed up" — that's not just an operational win. That's the moment your board and investors stop seeing AI as a cost center and start seeing you as the executive who turns complexity into predictable output. The confidence that comes from having those numbers — not from gut feeling, but from a defined test with a measurable result — is a different kind of calm than hoping the technology works out.
FAQ
What is GPT-6 Astra and how is it different from previous OpenAI models? GPT-6 Astra is OpenAI's most capable model to date, designed for complex end-to-end work including software engineering, legal and professional document work, computer use, and multi-step research. Compared to GPT-5.6 Sol, it scores significantly higher on complex task benchmarks like Terminal-Bench 4.0 (57.9% vs. 37.3%) and has substantially improved alignment properties — including 0% unauthorized scope violations in testing versus 48% for its predecessor.
Which industries are adopting GPT-6 Astra first? Based on OpenAI's published partnerships, the earliest enterprise adopters span travel and hospitality (Airbnb), legal AI (Harvey), and research infrastructure (Parallel). The common thread is not industry but process type: high-frequency, information-intensive workflows where context depth and reasoning quality directly determine output quality.
Do you need to be a large enterprise to benefit from GPT-6 Astra? No. GPT-6 Astra is available through OpenAI's standard API, ChatGPT Work, Codex, Microsoft Azure, and Amazon Bedrock. The access question is already solved. What determines whether a smaller organization benefits is the same thing that determines whether a large one does: whether they have a specific, well-defined process to apply it to, and whether their data and context are organized well enough to give the model something useful to work with.
What made Parallel's research cost reduction possible? Parallel's 50% reduction in both time and cost came from GPT-6 Astra's ability to issue more targeted search queries and reach useful results in fewer steps — reducing redundant API calls and token consumption. The model's efficiency also made it practical to distribute research tasks across multiple sub-agents working in parallel, which changed the economics of complex multi-source research workflows.
How does GPT-6 Astra's alignment improvement affect enterprise deployment? For organizations deploying AI in regulated or high-stakes environments — legal, financial, compliance — alignment is not a secondary concern. OpenAI's testing showed that GPT-6 Astra exceeded its authorized scope 0% of the time in controlled tests, compared to 48% for GPT-5.6 Sol without production safeguards. This makes it meaningfully more suitable for autonomous agent workflows where human oversight of every step is not practical.
What should a business do right now to prepare for GPT-6 Astra deployment? Identify one high-frequency process with clear inputs, outputs, and a measurable current baseline. Audit the quality and structure of the context that process would require — documents, data, knowledge sources. Define what success looks like before running the first test. Then run it, measure it, and report the number. That sequence is what separates the organizations publishing results from the ones still describing intentions.
The companies that moved first on GPT-6 Astra didn't do so because they had more resources or more risk tolerance. They moved first because they had already done the foundational work — the process clarity, the context infrastructure, the measurement discipline — that makes a new model immediately useful rather than theoretically promising. The window between "early adopter advantage" and "table stakes" closes faster with each model generation. The organizations that define their baseline today are the ones that will have a number to report when it matters.
Have questions? Ask the AI agent right now
Responds in seconds, knows everything about our services and will help with your situation
You might also like
GPT-6 Sol & Luna: AI Model Strategy for Business
GPT-6 Sol and Luna give CTOs a real choice between speed, cost, and quality. Here's how to match each model to the right business task.
EnterpriseClaude Broke Into OpenAI in 72 Hours
Claude attacked OpenAI's infrastructure via prompt injection — and succeeded in 72 hours. What this means for AI agent security in enterprise.
EnterpriseAn AI Hallucination Almost Started a War
AI hallucinations aren't just a technical bug. They can trigger real-world crises. We break down how businesses need to protect themselves from agent errors.