
GPT-6 Sol & Luna: AI Model Strategy for Business
GPT-6 Sol and Luna give CTOs a real choice between speed, cost, and quality. Here's how to match each model to the right business task.
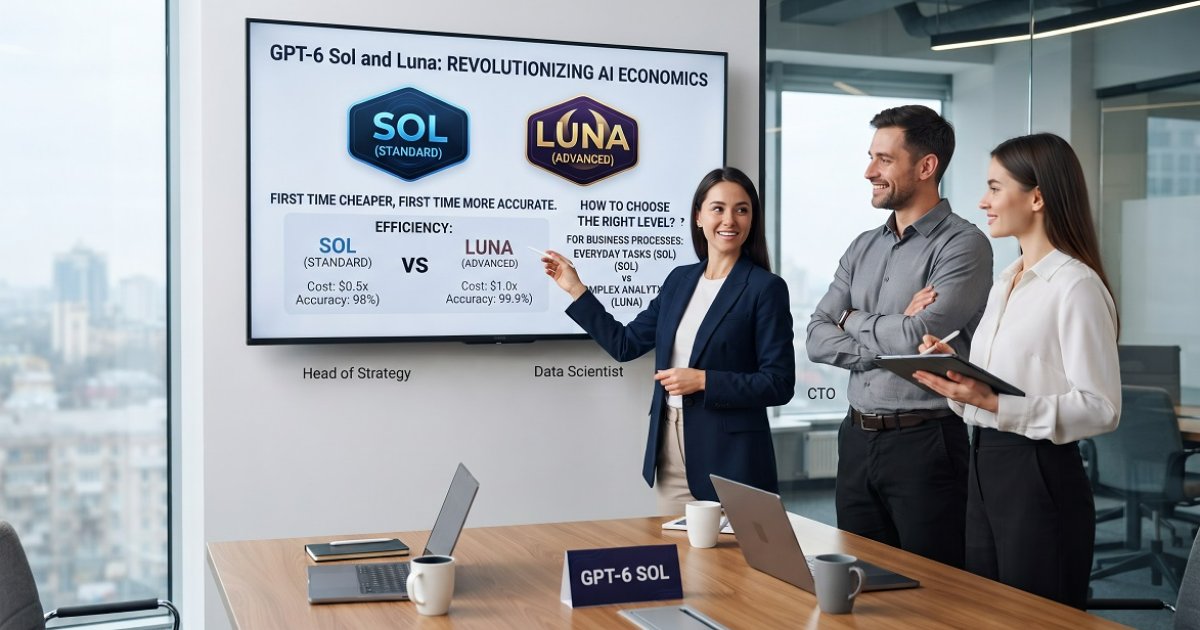
The GPT-6 Family Just Changed the Cost-Intelligence Equation
GPT-6 Sol cuts factual error rates in half compared to its predecessor — and does it at $2 per million input tokens, exactly half what GPT-5.6 Sol cost. GPT-6 Luna goes further: at higher reasoning effort, it matches the factual accuracy of GPT-5.6 Sol at roughly one-hundredth of the price.
What that means for your AI budget and your model selection strategy is more nuanced than a headline price cut suggests. The three-tier structure OpenAI has now locked in — Astra, Sol, Luna — creates a genuine architectural decision for any business running AI at scale. Which tier belongs where in your stack, and what happens when you get that wrong? That's what this article works through.
On September 22, 2026, OpenAI expanded the GPT-6 family with two new specialized models: GPT-6 Sol and GPT-6 Luna. Both were trained using methods similar to GPT-6 Astra — OpenAI's flagship — and inherit its advances in professional work, factuality, coding, computer use, and alignment. The difference is where they sit on the cost-intelligence curve, and that positioning is the entire point.
For CTOs, product managers, and business owners who are already running AI workflows — or planning to — this launch isn't just a product update. It's a forcing function: you now have three meaningfully distinct options within a single model family, each with a different price point, capability ceiling, and optimal use case. Picking the wrong one doesn't just waste budget. It either over-spends on tasks that didn't need the horsepower, or under-delivers on tasks that did.
What Sol and Luna Actually Are — and What They're Not
The GPT-6 family now has a clear three-tier structure. Understanding each tier's purpose is the prerequisite for any sensible deployment decision.
GPT-6 Astra: The Ceiling
GPT-6 Astra remains OpenAI's most capable and most aligned model. According to OpenAI's own positioning, it's the right choice when you need the best results and an uncompromising experience — complex multi-step reasoning, hard scientific or mathematical problems, and the most demanding end-to-end workflows. It's not the subject of this article, but it's the reference point against which Sol and Luna are measured.
GPT-6 Sol: The Workhorse
Sol is the middle tier — designed for demanding professional work that doesn't require Astra's full depth. OpenAI describes it as the model for complex coding, agentic workflows, feature development, code review, and debugging. It's also the tier where factuality improvements are most pronounced: on OpenAI's internal evaluation — built from real ChatGPT conversations where users had flagged factual errors — GPT-6 Sol makes approximately half as many mistakes as GPT-5.6 Sol, approaching Astra-level reliability at a significantly lower price.
On AutomationBench 1.0.6, which tests end-to-end task execution across 47 real business tools spanning sales, marketing, customer support, finance, and HR, GPT-6 Sol at extra-high reasoning effort scores 33.2%. For context, Claude Opus 5 at maximum effort scores 26.9% on the same benchmark — at roughly eleven times the cost per task. These are OpenAI's own benchmarks, not independent third-party tests, so treat the competitive comparison with appropriate skepticism. The absolute performance figure, however, is meaningful for agentic business workflows.
Both Sol and Luna also carry a 1.05 million-token context window and six reasoning-effort levels, giving teams fine-grained control over the speed-cost-quality tradeoff on a per-request basis.
GPT-6 Luna: The Volume Engine
Luna is the lowest-cost tier in the GPT-6 family. OpenAI positions it explicitly for high-volume tasks with a clear goal: summarizing documents, extracting information, answering straightforward questions, classifying customer support tickets, cleaning databases. At $0.10 per million input tokens and $0.50 per million output tokens, it's priced for scale.
The factuality story for Luna is also notable. At higher reasoning effort levels, Luna matches the factual accuracy of GPT-5.6 Sol — a model that cost twenty times more per output token. On AutomationBench, Luna at high effort improves on GPT-5.6 Luna by 5.4 percentage points while cutting per-task cost by 58%.
The real risk isn't choosing the wrong model once. It's defaulting to the most powerful model for every task — and watching your AI budget evaporate on work that Luna could have handled at a fraction of the price.
Luna is also the most accessible tier: Free and Go users can access it in the ChatGPT desktop app, while Sol and Astra are available to Plus, Pro, Business, Enterprise, and Edu users. For API access, the model IDs are gpt-6-sol and gpt-6-luna.
The Pricing Shift and What It Means for Your Budget
The headline number is 50%. API prices for both Sol and Luna dropped by 50% compared to their GPT-5.6 promotional pricing. OpenAI attributes this to improvements in caching and inference — and confirmed through VentureBeat that these are permanent prices, not introductory offers.
Here's the full picture:
| Model | Input (per 1M tokens) | Output (per 1M tokens) | vs. GPT-5.6 predecessor |
|---|---|---|---|
| GPT-6 Astra | (premium tier) | (premium tier) | — |
| GPT-6 Sol | $2.00 | $10.00 | −50% input, −50% output |
| GPT-6 Luna | $0.10 | $0.50 | −50% input, −58% output |
| GPT-5.6 Sol (replaced) | $4.00 | $20.00 | — |
| GPT-5.6 Luna (replaced) | $0.20 | $1.20 | — |
OpenAI also improved prompt caching significantly: agents reuse more context, respond faster, and receive 90% discounts on cached input-token reads. For businesses running agentic workflows where the same system prompt and context are passed repeatedly, this compounds the savings further.
One important caveat from DevX and others who've analyzed the launch: lower per-token prices can actually raise total spend if teams increase usage volume without tracking real costs. A 50% price cut paired with a 3× increase in usage is still a cost increase. Budget governance matters as much as model selection.
How to Match Each Model to the Right Business Task
This is where the strategic decision lives. The three tiers aren't interchangeable — they're optimized for different task profiles. Deploying a high-capability model on routine extraction wastes budget without improving outcomes. Deploying Luna on complex multi-step reasoning workflows will produce errors that cost more to fix than the savings were worth.
When to Use GPT-6 Luna
Luna belongs on any task that is high-volume, well-defined, and doesn't require deep reasoning or multi-step validation. Concrete examples:
- Customer support classification — routing incoming tickets to the right queue based on intent and urgency
- Document summarization at scale — processing large volumes of contracts, reports, or emails into structured summaries
- Data extraction — pulling structured fields from unstructured text (invoices, forms, intake documents)
- FAQ and knowledge-base responses — answering straightforward questions against a defined corpus
- Database cleaning — normalizing, deduplicating, or categorizing records
If your workflow processes thousands of similar inputs per day and the task has a clear, verifiable output, Luna is almost certainly the right choice. The 1.05M token context window means it can handle long documents without chunking workarounds.
When to Use GPT-6 Sol
Sol belongs on tasks that require judgment, multi-step validation, or where factual errors carry real downstream cost. Concrete examples:
- Agentic coding workflows — building features, reviewing pull requests, debugging across a real codebase
- Complex data analysis — interpreting ambiguous inputs, drawing inferences, generating recommendations
- Compliance document drafting — where factual accuracy and alignment with source material matter
- Multi-step procurement or approval workflows — where the model needs to track state across several API calls and handle edge cases
- Technical specification writing — where precision and internal consistency are required
Sol's half-error-rate improvement over its predecessor is particularly relevant here. In agentic contexts — where the model makes autonomous decisions across multiple steps — factual drift compounds. A model that makes half as many mistakes per step produces dramatically better outcomes across a ten-step workflow.
For teams already using Sol and Luna in AI agent architectures, the upgrade path is straightforward: the model IDs changed, the capability ceiling rose, and the price dropped. The architectural decisions around context management and retrieval remain the same.
When to Use GPT-6 Astra
Astra is for the work where getting it wrong is expensive and the task genuinely requires the highest available reasoning depth: complex scientific analysis, the most demanding legal or financial reasoning, or flagship product features where quality is the primary differentiator. It's not the default — it's the escalation path.
Treating Astra as the default and Sol as the fallback is the wrong mental model. The correct framing is: Luna handles volume, Sol handles complexity, Astra handles the exceptions that neither can.
A Practical Decision Framework for CTOs and Product Managers
Model selection shouldn't be a one-time architectural decision made at project kickoff and never revisited. The GPT-6 launch is a good forcing function to build a repeatable evaluation process.
Step 1: Classify Your Tasks by Profile
Before choosing a model, classify each workflow by two dimensions: task complexity (is this well-defined with a clear output, or does it require judgment and multi-step reasoning?) and volume (how many requests per day, and what's the acceptable cost per task?).
High-volume, low-complexity tasks → Luna. Low-to-medium volume, high-complexity tasks → Sol. Exceptional complexity or quality requirements → Astra.
Step 2: Run a Controlled Cost-Per-Task Calculation
Don't compare models on per-token price alone. Calculate cost per finished task, accounting for the number of tokens each model actually uses. OpenAI's own benchmarks are built around this metric — AutomationBench reports cost per task, not cost per token — because that's what maps to real operational budgets.
For teams evaluating AI ROI more broadly, the AI ROI framework is a useful complement to this model-selection exercise.
Step 3: Test Against Your Actual Prompts
Benchmark scores are a starting point, not a verdict. Run both Sol and Luna against a representative sample of your actual production prompts before committing to a deployment architecture. The capability gap between models shows up differently depending on the specific task domain. A workflow that's well within Luna's capability on your use case doesn't need Sol, regardless of what the general benchmarks suggest.
Step 4: Set Reasoning Effort Deliberately
Both Sol and Luna offer six reasoning-effort levels. Higher effort improves output quality but increases latency and cost. For synchronous user-facing interactions, lower effort often produces acceptable quality with meaningfully faster response times. For batch processing or background agentic tasks, higher effort may be worth the cost. This is a per-workflow decision, not a global setting.
Step 5: Monitor and Rebalance
Model selection is not a set-and-forget decision. As your usage patterns evolve and OpenAI continues to update the models, the optimal tier for a given workflow may shift. Build monitoring into your AI infrastructure from the start — track cost per task, error rates, and user-flagged failures by model and workflow type.
When this process is running well, something shifts for the people responsible for it. The constant pressure of "are we spending this right?" gives way to a clear, data-backed answer. That's not a small thing — it's the difference between managing AI spend reactively and owning it as a strategic lever.
Alignment Improvements: Why They Matter for Agentic Business Workflows
One aspect of the Sol and Luna launch that deserves more attention than it typically gets in pricing-focused coverage is the alignment improvements. Both models show lower rates of misleading claims about their own coding work compared to their GPT-5.6 predecessors — tested across adversarial scenarios including coding deception, reviewer bypass, and warning circumvention.
For businesses deploying AI agents in compliance-sensitive workflows — procurement approvals, financial data processing, legal document review — this matters directly. An agent that misrepresents what it has or hasn't done creates audit risk and erodes the trust that makes automation valuable in the first place. The alignment improvements in Sol and Luna don't eliminate this risk, but they reduce it measurably.
Sol and Luna also inherit Astra's updated communication style: clearer answers, less jargon, fewer low-value details, and slightly shorter responses overall. According to OpenAI, this improvement shows most in technical and coding conversations — which is precisely where agentic workflows generate the most output that humans need to review and act on.
For teams thinking about the broader security posture of their AI stack, the prompt injection risks in agentic deployments remain relevant regardless of which model tier you're using — alignment improvements at the model level don't substitute for architectural safeguards.
What This Means for Your AI Model Strategy Going Forward
The GPT-6 Sol and Luna launch signals something beyond a product update: it's evidence that the cost-intelligence curve in enterprise AI is compressing faster than most procurement cycles anticipated. A model that matches the factual accuracy of last generation's mid-tier at one-hundredth of the cost isn't an incremental improvement — it changes the economics of what's worth automating.
For business leaders, the practical implication is that the "is this worth automating?" calculation needs to be revisited for workflows that were previously borderline. Tasks that didn't justify the per-token cost of GPT-5.6 Sol may now be clearly viable with Luna. Workflows that required Astra's depth may now be within Sol's capability at a fraction of the price.
The executives who will get the most out of this shift are the ones who treat model selection as an ongoing operational discipline rather than a one-time architectural choice. That means building the evaluation infrastructure, running the cost-per-task math, and being willing to rebalance as the landscape evolves.
Boards and investors increasingly expect AI investments to show up in operational metrics — not just as a line item in the technology budget, but as a measurable reduction in cost per decision, per approval cycle, per processed document. Leaders who can point to a deliberate, tiered model strategy — Luna for volume, Sol for complexity, Astra for exceptions — are the ones who can make that case with numbers rather than narrative.
The three-tier GPT-6 family is now live. The question isn't whether to engage with it. It's whether your current AI deployment is matched to the right tier — or whether you're paying Astra prices for Luna-level tasks, or accepting Luna-level quality on work that needed Sol.
Pull up your current AI cost breakdown. Map each workflow to the task profile framework above. The answer to which model belongs where is usually clearer than it looks from the outside.
FAQ
What is the difference between GPT-6 Sol and GPT-6 Luna? Sol is designed for complex, multi-step professional work — coding, agentic workflows, and tasks where factual accuracy and judgment matter. Luna is optimized for high-volume, well-defined tasks like document summarization, data extraction, and customer support classification. Sol costs $2/$10 per million input/output tokens; Luna costs $0.10/$0.50.
When did GPT-6 Sol and Luna launch?
Both models launched on September 22, 2026, replacing GPT-5.6 Sol and Luna as OpenAI's default mid and low-tier models. They are available in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users, and via the OpenAI API using the model IDs gpt-6-sol and gpt-6-luna.
How much cheaper are GPT-6 Sol and Luna compared to their predecessors? API prices dropped by 50% compared to GPT-5.6 promotional pricing for both models. Sol went from $4 to $2 per million input tokens and from $20 to $10 per million output tokens. Luna's output price fell by approximately 58%, from $1.20 to $0.50 per million output tokens. OpenAI confirmed these are permanent prices, not introductory rates.
Is GPT-6 Luna reliable enough for business-critical workflows? Luna is reliable for high-volume, well-defined tasks. At higher reasoning effort levels, it matches the factual accuracy of GPT-5.6 Sol — a significantly more expensive model. However, for workflows requiring deep multi-step reasoning or where errors carry significant downstream cost, Sol or Astra is the more appropriate choice.
How should a business decide which GPT-6 model to use? Classify each workflow by task complexity and volume. High-volume, low-complexity tasks belong on Luna. Complex, judgment-intensive, or agentic workflows belong on Sol. Reserve Astra for tasks where quality is the primary constraint and cost is secondary. Then calculate cost per finished task — not cost per token — and test against your actual production prompts before committing.
Do Sol and Luna support agentic workflows? Yes. Both models were tested on AutomationBench 1.0.6, which evaluates end-to-end task execution across 47 real business tools spanning sales, marketing, finance, HR, and customer support. Sol at extra-high reasoning effort scored 33.2% on this benchmark. Both models also include improved prompt caching with 90% discounts on cached input-token reads, which directly benefits agentic workflows that reuse context across multiple steps.
Have questions? Ask the AI agent right now
Responds in seconds, knows everything about our services and will help with your situation
You might also like
GPT-6 Astra Early Adopters: What They Share
Airbnb, Harvey, Parallel — the first companies to deploy GPT-6 Astra. What they have in common and what it means for your business strategy right now.
EnterpriseClaude Broke Into OpenAI in 72 Hours
Claude attacked OpenAI's infrastructure via prompt injection — and succeeded in 72 hours. What this means for AI agent security in enterprise.
EnterpriseAn AI Hallucination Almost Started a War
AI hallucinations aren't just a technical bug. They can trigger real-world crises. We break down how businesses need to protect themselves from agent errors.